LM Warden
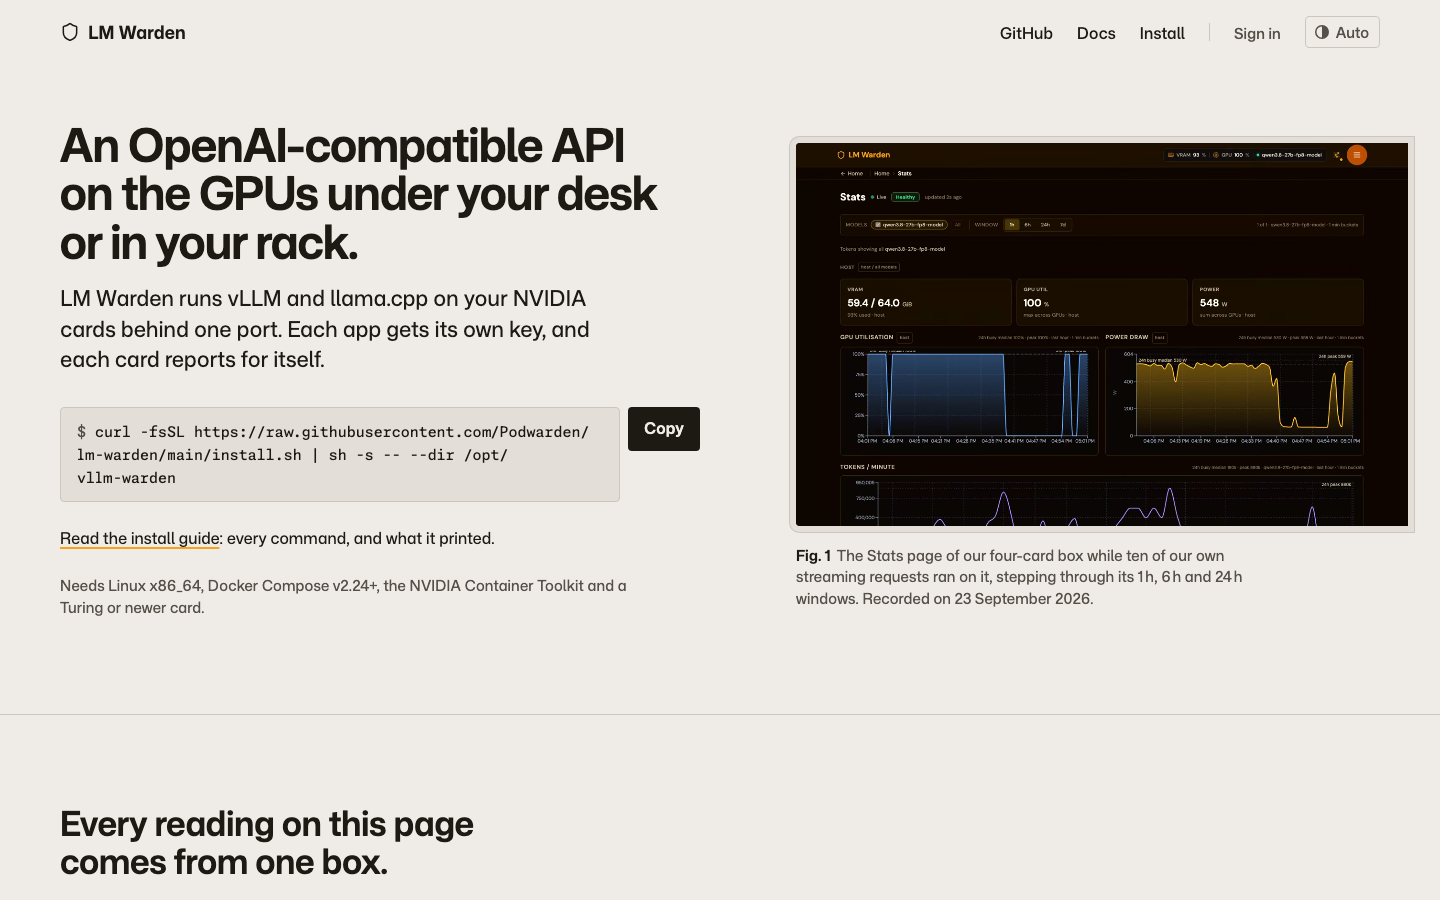
LM Warden 在自有 NVIDIA GPU 上运行 vLLM 和 llama.cpp,对外只暴露一个 OpenAI 兼容端口,每个应用一把密钥,每张卡单独上报显存、利用率和功耗。
Project analysis is shown in its source language.
Developer ToolsArtificial IntelligenceDeveloper ToolsSaaS
Discovery source
First added in the .com report on Sep 26, 2026
Project insights
- Value proposition
- 桌下或机柜里的 GPU 立刻变成带密钥和读数的本地推理网关。
- Problem solved
- 团队有卡却要把 vLLM、llama.cpp 和用量监控拼成一套接口。
- Pricing model
- 开源安装脚本,自托管,官网未标订阅价
- Target persona
- 有 NVIDIA GPU、要自建 OpenAI 兼容接口的团队
- Business type
- B2B
Screenshots